I use AI to work on everything physical, in more ways than one (my gym membership being the notable exception). This fascination with the physical world has led me to tackle many different problems with reinforcement learning and generative models. For several years, I worked on the physics of wireless signal propagation and on chip design, specifically physical design. Currently, my main focus is physical AI: robots that walk, grasp and carry, with an emphasis on locomotion, loco-manipulation and sim-to-real transfer.
In my free time, you can find me playing the piano🎹, practicing meditation🧘, reading philosophy📙 and thinking about artificial general intelligence (preferably on the beach🏖️).
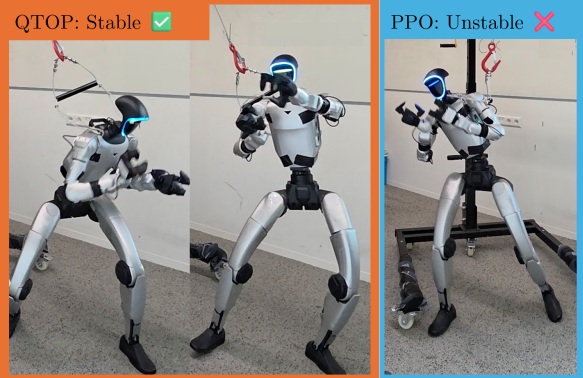
QTOP improves the sample efficiency of RL humanoid motion tracking with a distributional, quantile-based advantage estimate, beating on- and off-policy baselines by up to 10% in simulation and on real robots, scaling predictably with compute.
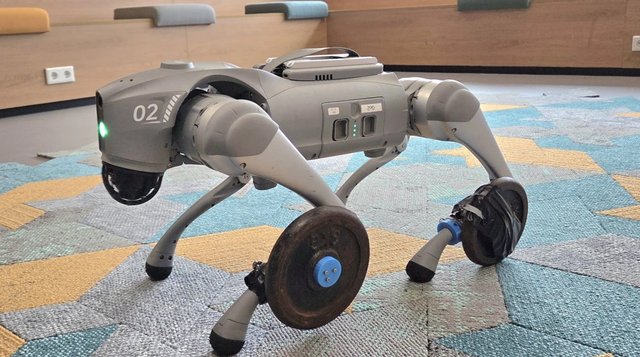
TEMPO adapts RL locomotion policies online when deployment conditions change, using entropy-regularized, memory-guided policy optimization, with gains of up to 80% on Go1, Go2 and G1 and validation on a real Go2 carrying extra payload.
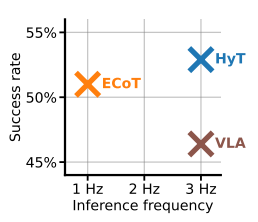
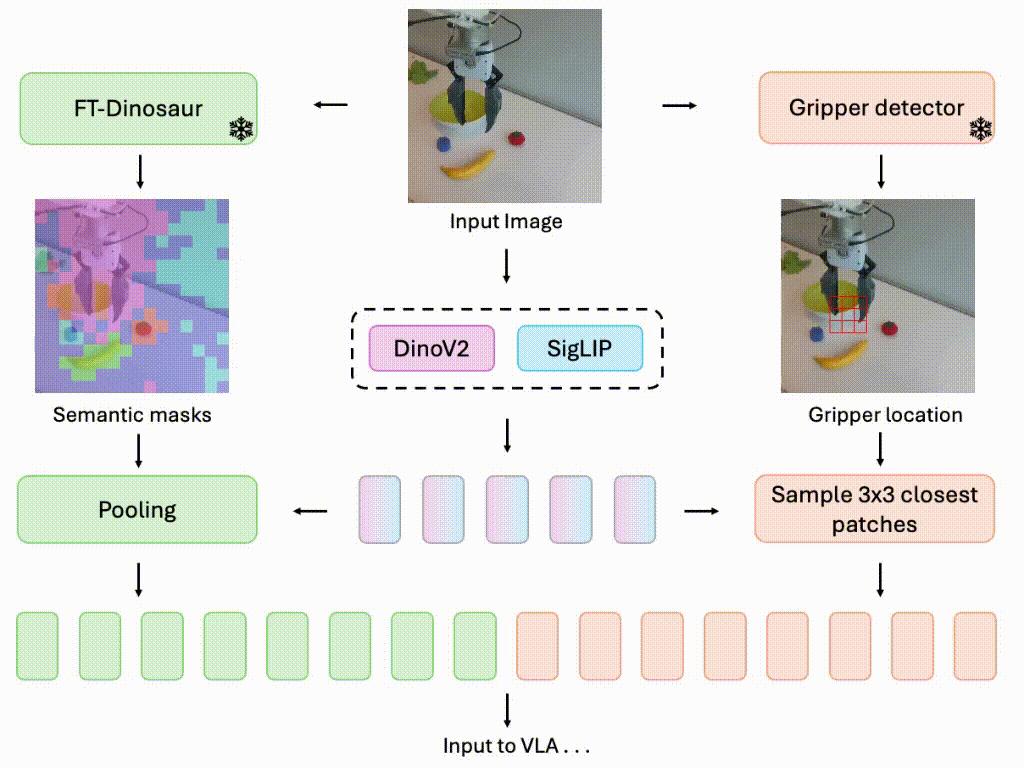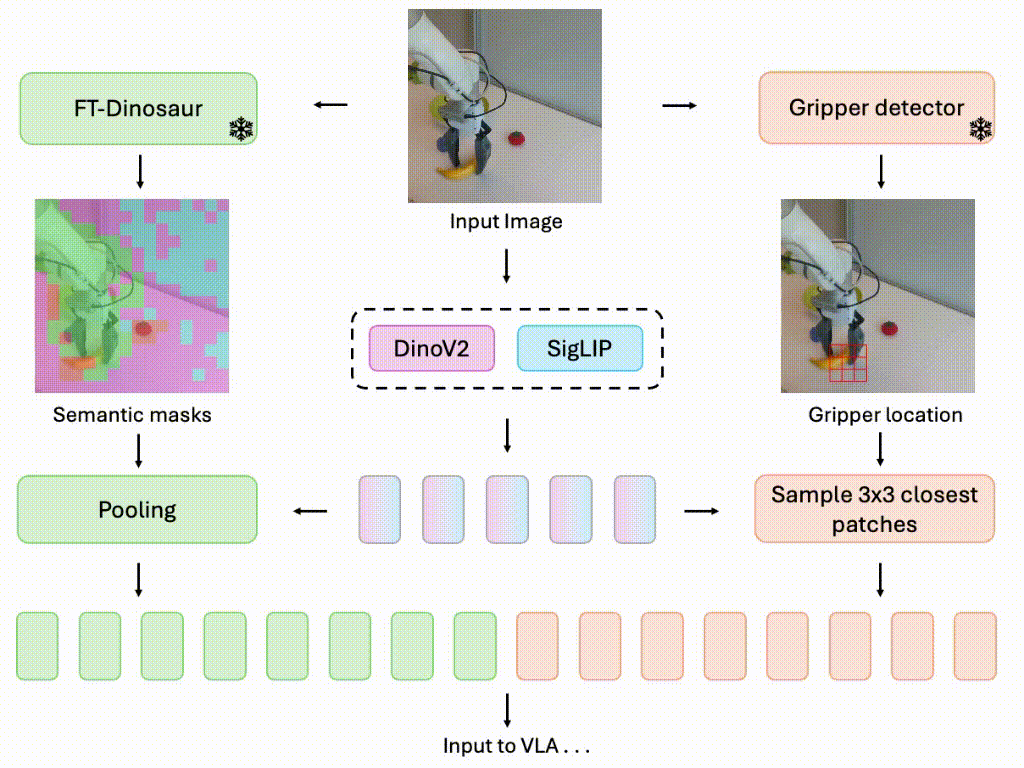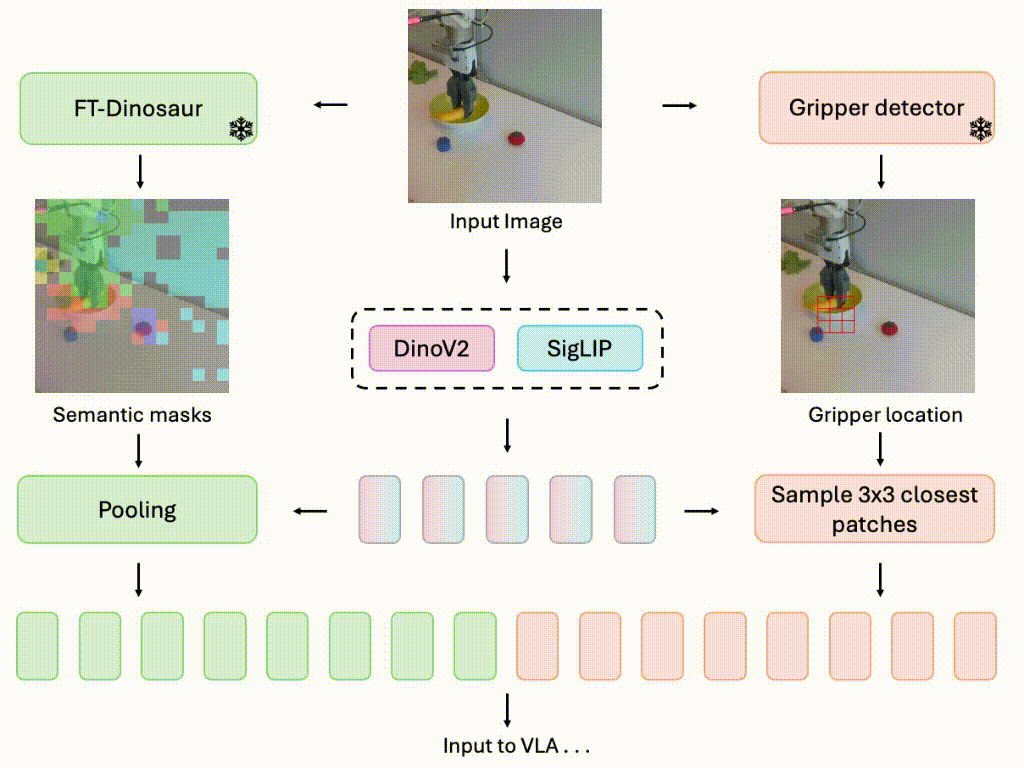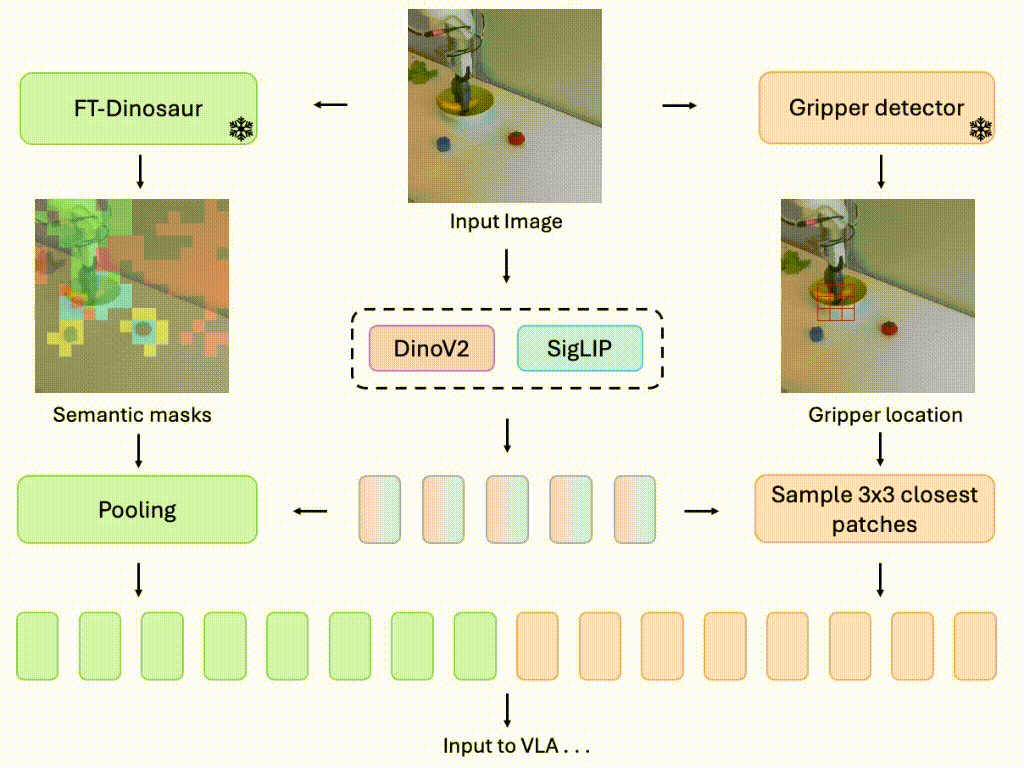
Hybrid Training (HyT) lets Vision-Language-Action models learn from chain-of-thought reasoning to boost performance while allowing faster, thought-free inference when needed.
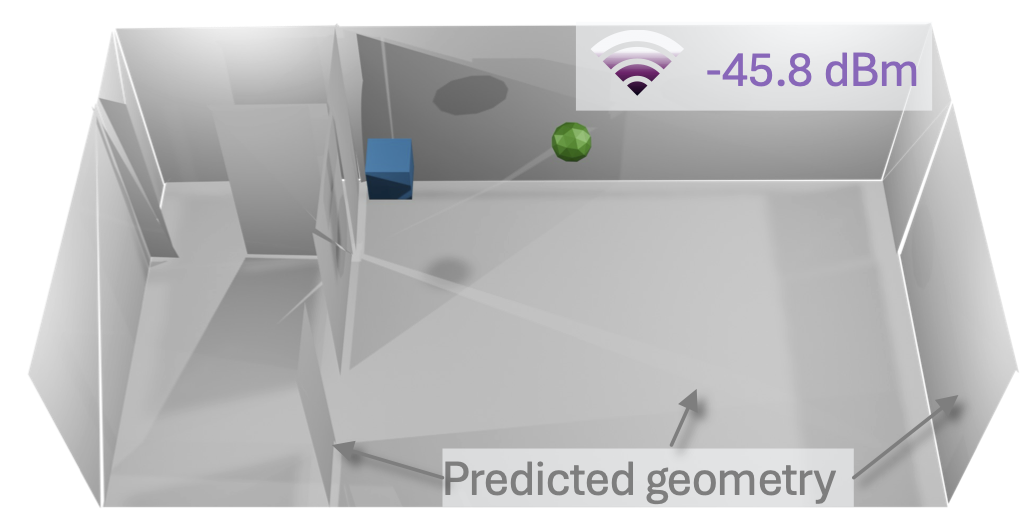
A Geometric Algebra Transformer "WiGATr" for learning an E(3) equivariant simulator of wireless signal transmission. We test WiGATr as a predictive model as well as a diffusion model of signal and 3D geometry.
AI alignment is challenging due to a multitude of different and possibly conflicting values present in human feedback. We propose to overcome this challenge with a multi-objective agent that actively learns user preferences.